Ecreate HTML Importer – Bulk Post And Page Import From HTML, Word And PDF Wordpress Plugin - Rating, Reviews, Demo & Download
Plugin Description
Bulk post import and page import for WordPress. Moving an old static site into WordPress usually means copying and pasting page after page. This plugin does it in one go: put your HTML files in a ZIP, upload it, look through what the importer found, and approve the ones you want. Every file becomes a post, or a page if that is what you are rebuilding.
Nothing is created until you say so. That is the main idea. The importer reads your files into a review list first, shows you the title, the address and the content it worked out for each one, lets you pick the category, and lets you correct anything before a single post exists.
It also reads Word documents and PDFs, so a folder of .docx reports or policy PDFs can become posts the same way.
Simple by default
There is no settings page. Everything an importer normally asks for up front is worked out from your files instead:
- The title comes from the h1, or the page title, or the file name
- The content is the main block of writing, with the menu, header, footer and sidebar removed
- Everything becomes a post. Choose pages instead if you are rebuilding a website
- Categories are chosen by you on the review screen, for a whole file type at once or one file at a time
- The file name becomes the address, so your old links can be redirected to the new ones
- The meta description becomes the excerpt
Every one of those is shown in the review list and can be changed there, one at a time or in bulk. The advanced panel is there if you need it, and you can ignore it.
What you can put in the ZIP
Mix as many of these as you like in one archive:
- Web pages: .html, .htm, .xhtml
- Word documents: .docx (older .doc files have to be saved as .docx in Word first)
- PDF files: .pdf, with text in them. A scanned PDF is reported rather than imported
The simplest way to arrange a ZIP, which is also how the sample one is arranged. Only the documents are needed; the images folder is optional, and only web pages ever use one, because Word and PDF files are opened and their pictures taken straight out of them:
your-blog-post.zip
  html/              your .html, .htm and .xhtml pages
    images/          optional: the pictures those pages use
  docx/              your Word files, pictures and all
  pdf/               your PDF files, pictures and all
Your ZIP does not have to look like that. Any folders work, including the ones your old site already uses, and files in the root of the ZIP are fine too. Folders only keep your files tidy; they do not change what is imported. The upload screen shows this as well, so you do not have to remember it.
Pictures look after themselves. A web page has its pictures fetched from the address it points at, or taken from the ZIP if you kept the images folder in there. Word and PDF files carry their pictures inside them. Everything else, such as stylesheets and scripts, is ignored and never written to your server.
Try it with the sample files
The upload screen has a Download the sample ZIP button. It gives you a small archive with one folder per kind of file, and nothing else in it:
- html/ three web pages: welcome.html, about-us.htm and desks.xhtml
- docx/ a Word file with heading styles, lists, bold, italic, a table and a picture
- pdf/ a PDF with real text in it
Upload it straight back and you can see exactly what an import does, and what the review screen looks like, before using your own files. The three web pages are built three different ways on purpose, because real sites are not all alike: one uses divs, one uses modern HTML5 sections, and one is laid out inside a table.
The sample is built on your own server when you ask for it, so there are no sample files sitting in the plugin taking up space.
What it imports
- HTML: headings, paragraphs, lists, tables, quotes, code and images. Menus, headers, footers, sidebars, scripts and tracking code are stripped out.
- Word (.docx): Word heading styles become real headings, bullet and numbered lists stay lists, bold and italic survive, tables come across, and pictures inside the document are copied into your media library.
- PDF: the text is read and turned into headings and paragraphs as far as a PDF allows. See the honest note below.
Modern content, not a blob of HTML
Imported content is written as real block editor blocks by default, so it can be edited like anything else you write in WordPress. If your site uses the classic editor, you get clean HTML instead. If Elementor is active, pages can be built as Elementor widgets, ready to open in the editor.
Images and links
Pictures look after themselves, whichever way they are stored:
- A page pointing at a file in the ZIP, such as images/photo.jpg, uses that file
- A page pointing at a full web address has the picture fetched from there, which is the only copy a page copied out of a browser has. This can be turned off in the advanced settings
- Word and PDF files carry their pictures inside them, so nothing extra is needed
Each picture is copied into the media library once, however many pages use it, and the first picture on a page can become its featured image. Links between the imported pages are pointed at their new addresses once everything exists.
Undo
Every post the importer creates is marked with the import it came from, so the finished screen offers to undo the whole thing. That deletes exactly those posts, for good, and touches nothing else on your site. They are not left in the trash, because an import of a few hundred files would leave a few hundred things to clear out by hand. The screen asks before it does it.
Built for big imports and small hosting
Files are read and created a few at a time, with a progress bar, so a ZIP of five hundred pages finishes on ordinary shared hosting instead of hitting the time limit. You can leave the page and come back; the import stays where it is.
Honest about PDFs
A PDF does not contain a document. It contains instructions for drawing text at positions on a page, with no headings and no paragraphs. Those have to be worked out from the size and position of the text, so PDF results are a good guess rather than a certainty. That is exactly why the review step exists.
A scanned PDF holds pictures of text rather than text. Reading one needs character recognition, which WordPress cannot do, so the plugin tells you that the file was scanned and leaves it out rather than creating an empty post.
Need more?
We build and migrate WordPress sites for a living. If you have an old site to move, with redirects, templates and theming to match, tell us about it and we will tell you what it takes.
Screenshots
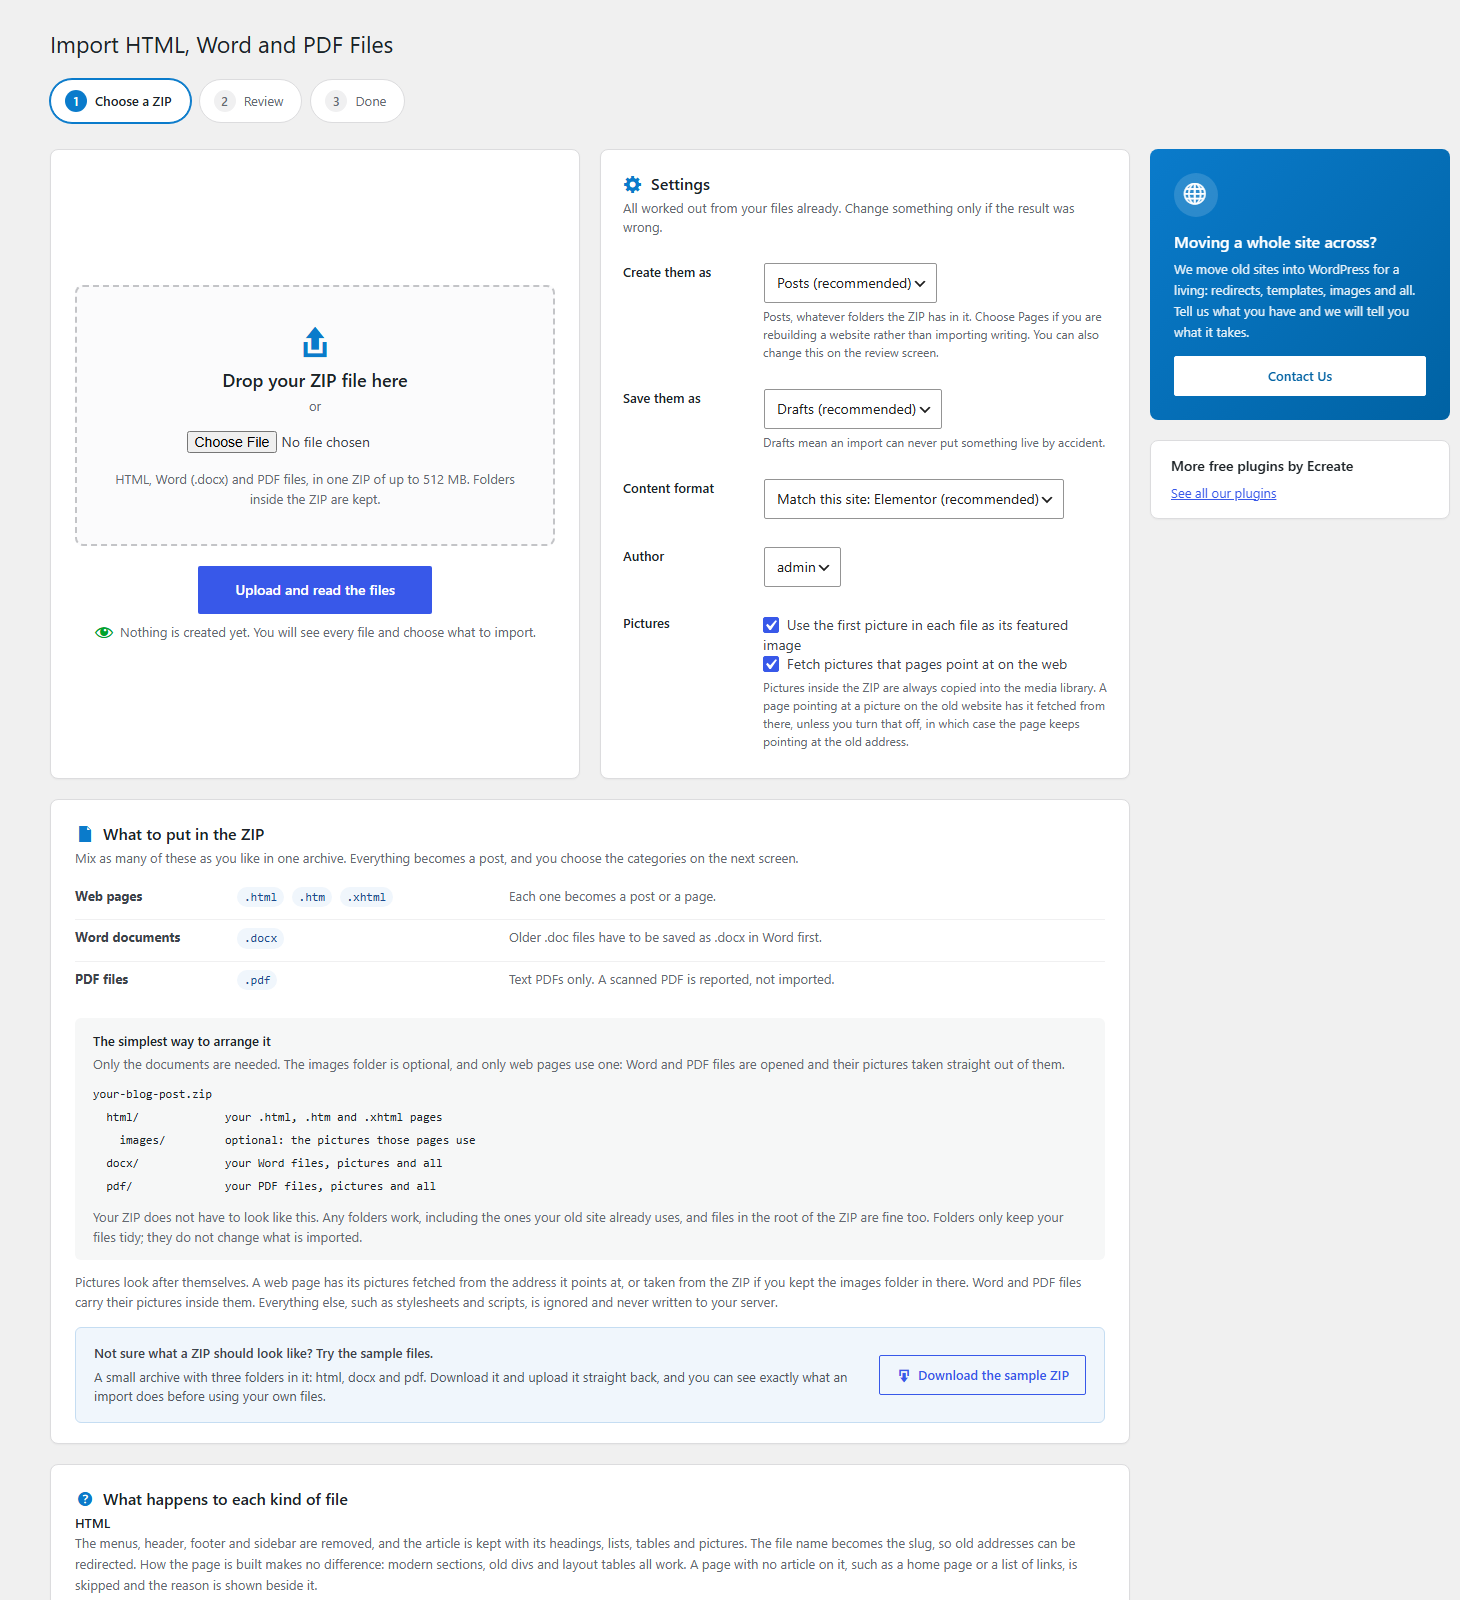
Step one: drop in a ZIP of HTML, Word or PDF files. Everything else is worked out for you.
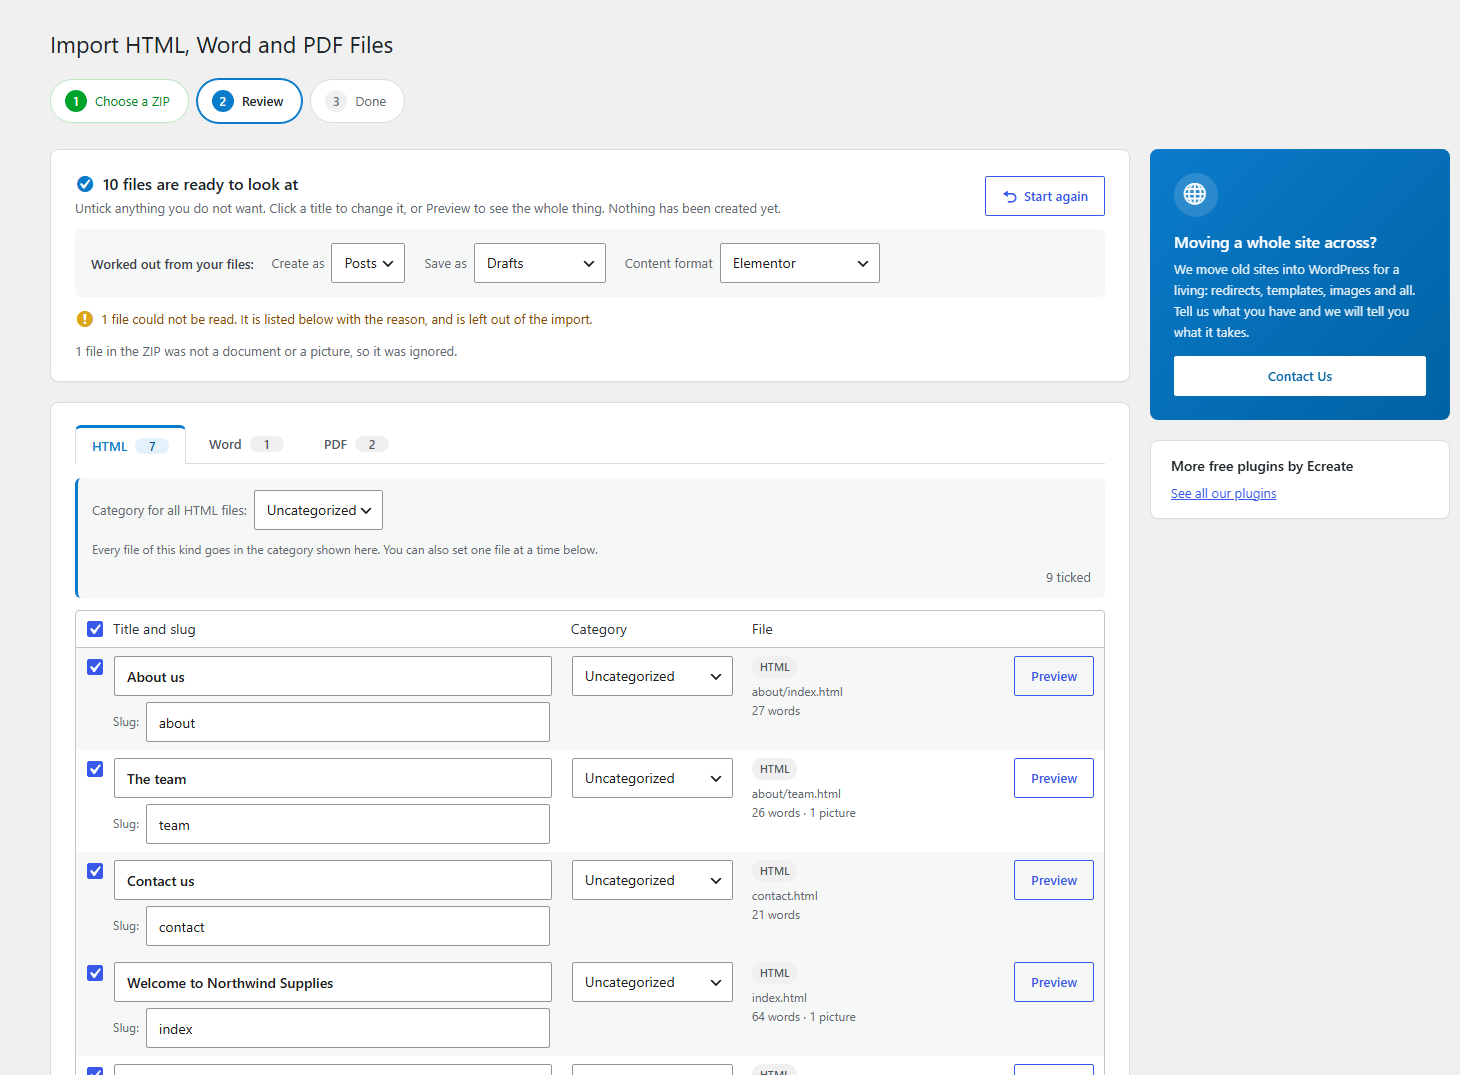
The review list: every file with the title and address that were found, a category to choose for a whole file type or one file at a time, and nothing created yet.
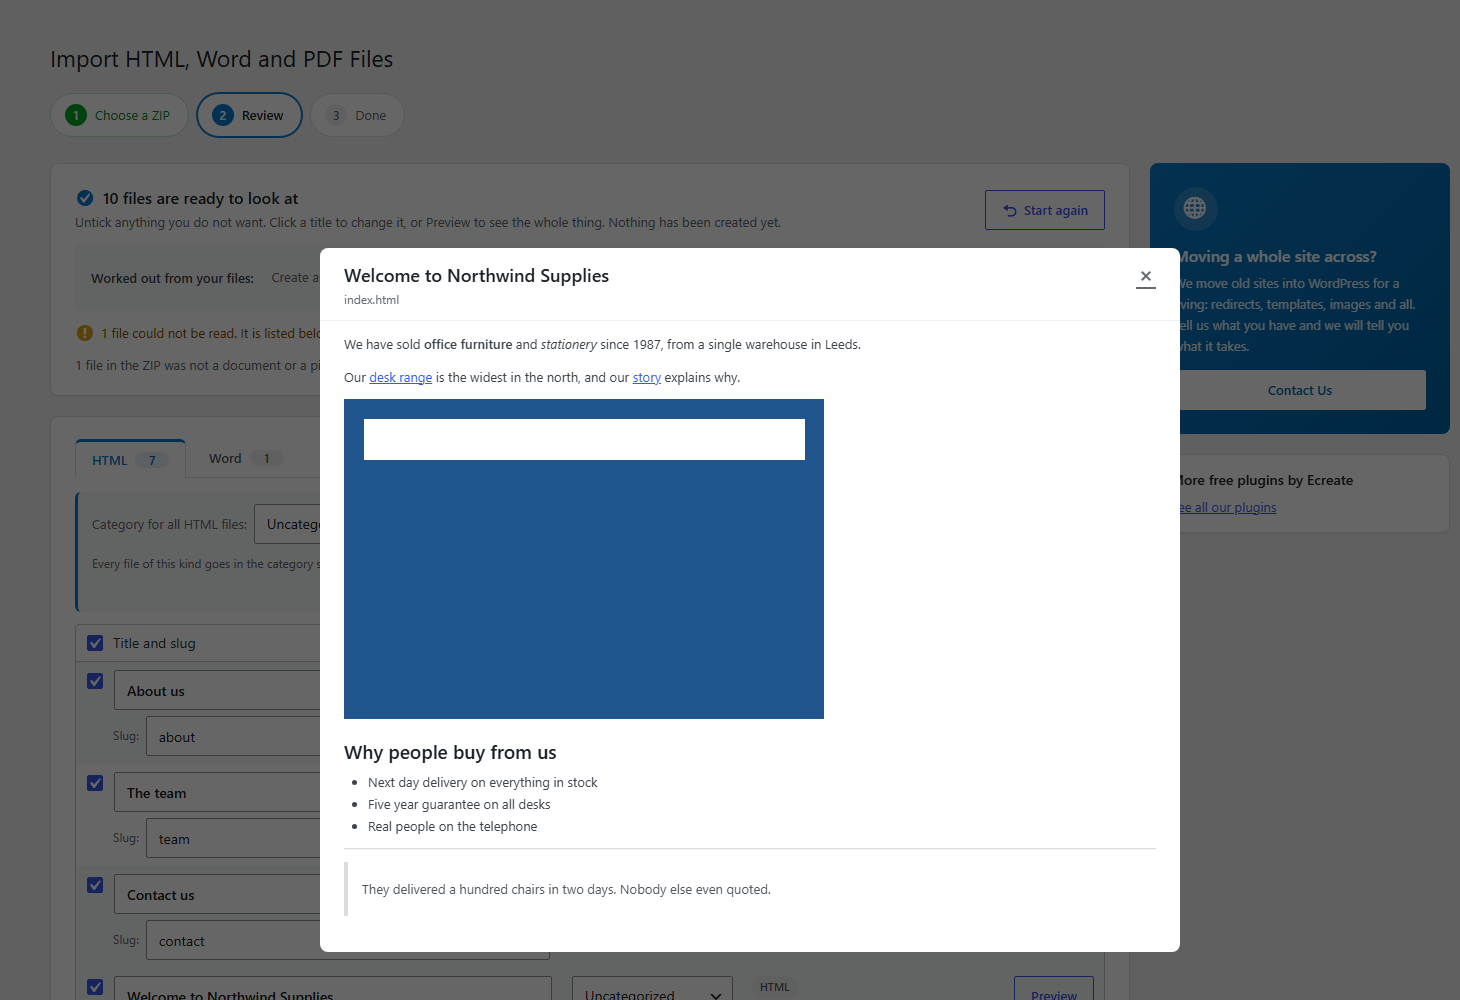
The preview: see a file exactly as it would be imported before approving it.
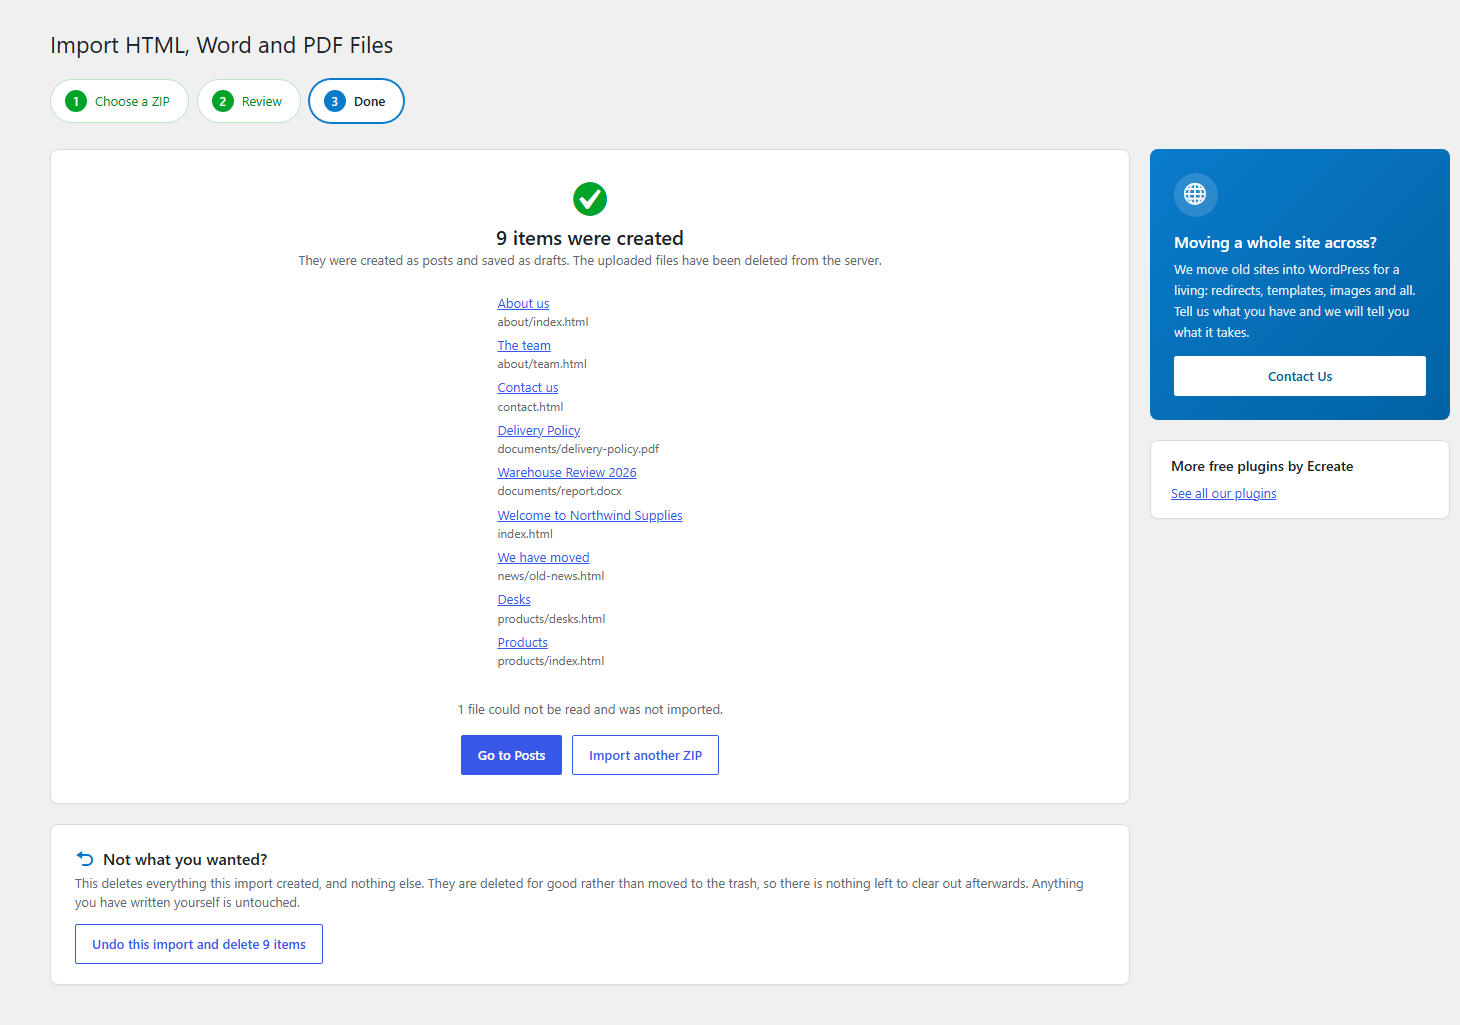
The finished screen, with links to what was created and a one click undo.